118. Equilibrium Search and Unemployment#
In addition to what’s in Anaconda, this lecture will need the following libraries:
!pip install quantecon
118.1. Overview#
This lecture studies Lucas and Prescott [1974], the labor-market companion to the paper on investment that we studied in Investment Under Uncertainty.
The two papers were written by the same authors at the same place within a few years of each other, and they use the same tools: a Bellman equation solved by successive approximations, Blackwell’s theorem, and a Markov process whose invariant distribution describes the long run.
What changes is the question.
The question is one that the search literature of the 1960s had raised but could not answer.
Job Search I: The McCall Search Model describes that literature’s central problem: a worker draws wage offers from a known distribution and decides when to stop searching.
It is a model of an individual, and it takes the wage distribution as given.
But where does the distribution come from?
Lucas and Prescott set out to answer that, and discovered that the answer requires a general equilibrium model:
optimal labor supply behavior and the wage distribution on which it is based must be simultaneously determined within a model of market (as opposed to individual) behavior.
They build an economy of many spatially separate markets – “islands” – each with its own randomly shifting demand for labor.
Workers in a market can work at the wage that clears it, or leave.
Leaving means earning nothing this period and arriving somewhere else next period, so unemployment is the act of moving between markets.
Everything is competitive, everyone optimizes, and expectations are rational in the sense of Muth [1961]: the distribution that workers use to evaluate their prospects is the one that their own decisions generate.
The paper’s central object is a single number, \(\lambda\), the expected present value of search.
An individual market takes \(\lambda\) as given, in the way a competitive firm takes a price as given.
Economy-wide, \(\lambda\) adjusts until the workforce that markets want to hold equals the workforce the economy has.
In equilibrium some markets always have more workers than they want to employ, so
Note
Unemployment is positive in every period.
Lucas and Prescott argue that this unemployment need not signal an inefficiency, and the argument is worth stating in their terms, although the paper proves no welfare theorem, leaves open whether actual labor markets have important external effects, and this lecture proves nothing either.
There is no congestion externality in the model and no wage rigidity.
The searching worker who crowds his fellows does so in the same way that any seller of a good crowds other sellers, and \(\lambda\), like any other equilibrium price, signals what the paper calls “the correct social return” to an additional searcher.
Let’s start with some imports:
import numpy as np
import matplotlib.pyplot as plt
import quantecon as qe
from collections import namedtuple
118.2. The economy#
There are many markets, indexed by the state of demand in them.
Demand shifts are independent across markets, so that aggregate demand is constant, and persistent within a market, so that today’s demand tells a worker something about tomorrow’s.
In each market a competitive industry produces a single good with labor as the only input.
If \(p = D(s, Q)\) is the inverse demand curve in demand state \(s\) and \(q(n)\) is the production function of each of the \(m\) identical firms, then profit maximization sets the wage equal to the marginal value product of labor, and the function
summarizes everything about the demand side of this labor market.
Lucas and Prescott discard \(D\) and \(q\) and place assumptions directly on \(R\): it is positive, bounded and differentiable, with
The demand state \(s\) follows a Markov process with transition density \(f(s', s)\) possessing a unique stationary distribution.
118.2.1. Timing#
A market begins a period with a workforce \(y\), which is the most it can employ.
Then, within the period:
demand \(s\) is realized and the labor market clears, employing \(n \le y\) workers at the wage \(w = R(s, n)\)
the \(y - n\) workers who are not employed earn nothing and join the pool of searchers
employed workers remain in the market into next period; searchers are allocated across markets and arrive next period
So a worker is unemployed for exactly one period each time he moves, and the unemployed are workers in transit.
118.2.2. The value of search#
Because demand shifts are independent across markets and there are many of them, the economy-wide distribution of workers across markets is constant even though each market’s workforce fluctuates.
A searcher’s prospects therefore do not depend on the market he is leaving, and the expected present value of search is a single number \(\lambda\).
Searchers are allocated to markets in a way that equalizes the expected value of arriving, so no market offers an arriving worker more than \(\lambda\).
We take \(\lambda\) as given for now and determine it in Economy-wide equilibrium.
118.3. A worker’s problem#
Let \(v(s, y, \lambda)\) be the expected present value of the earnings of a worker who finds himself in a market with demand \(s\) and workforce \(y\) at the start of a period, and let \(\beta \in (0,1)\) be the discount factor.
Lucas and Prescott arrive at a functional equation for \(v\) by considering three cases.
Case A: some workers leave. Departing workers get \(\lambda\). The workers who stay can have no more, since the leavers could have stayed, and no less, since they could have left. So \(v = \lambda\).
Case B1: all workers stay and no new workers arrive. Current employment is \(y\), the wage is \(R(s,y)\), and next period’s workforce is still \(y\):
Case B2: all workers stay and new workers arrive. Arriving workers are searchers, so the continuation value of being in this market next period must be exactly \(\lambda\):
Cases B1 and B2 differ according to whether the continuation value at the unchanged workforce exceeds \(\lambda\), and in case A the worker takes \(\lambda\).
All three collapse into one equation:
Equation (118.2) repays a careful look, because its two operators do different jobs.
The max is the worker’s own option: he can always leave and collect \(\lambda\).
The min is not the worker’s choice at all.
It is a restriction that competition among searchers imposes: if the continuation value in this market exceeded \(\lambda\), searchers would flow in until it did not.
Proposition 118.1
For each \(\lambda\), equation (118.2) has a unique bounded continuous solution \(v\), and successive approximations converge to it from any starting point.
The solution is nondecreasing in \(s\) and in \(\lambda\) and nonincreasing in \(y\).
The proof is the one used throughout Investment Under Uncertainty: the operator defined by the right side of (118.2) is monotone and satisfies a discounting condition, so Blackwell’s theorem [Blackwell, 1965] applies.
That \(v\) is nonincreasing in \(y\) is worth a word: a worker is worse off the more crowded his market, because a larger workforce means a lower marginal product and a lower wage.
118.4. Employment, wages, and two thresholds#
With \(v\) in hand, the rest of a market’s behavior follows from two threshold rules.
118.4.1. How many work#
Let \(\bar n(s, \lambda)\) be the employment at which the marginal worker is just indifferent between staying and searching:
The left side is what a worker gets by staying when employment and next period’s workforce are both \(\bar n\): this period’s wage plus the discounted continuation.
It is non-increasing in \(\bar n\).
Once a market is so crowded that the marginal product has reached zero, the value of being there has fallen to \(\lambda\) and the left side is flat at \(\beta \lambda < \lambda\), so (118.3) cannot hold there.
On the integer workforce grid used below, (118.3) rarely holds with equality, and employment is the largest \(\bar n\) at which the left side is at least \(\lambda\).
Employment is then
and unemployment in this market is \(y - n\), which is positive exactly when the workforce exceeds \(\bar n\).
118.4.2. How many arrive#
A market attracts searchers only when it employs its whole workforce and the continuation value still exceeds \(\lambda\).
Let \(\bar y(s,\lambda)\) be the workforce at which that stops being true:
Arrivals fill a market up to \(\bar y(s, \lambda)\) and no further.
Note that \(\bar y \le \bar n\), since \(R \ge 0\) means that any workforce whose continuation alone covers \(\lambda\) also covers it once the wage is added.
The inequality is strict wherever the marginal product is positive: a market just worth entering for a searcher is then strictly inside the range where everyone works.
In the worst demand states of the calibration below both thresholds are zero, and the market employs nobody and attracts nobody.
118.4.3. Three regions, one transition law#
Together, (118.4) and (118.5) partition the \((s,y)\) plane into the three regions of the paper’s Figure 3, and they give the law of motion for the workforce a very simple form:
A market that is too crowded sheds workers down to \(\bar n(s,\lambda)\); a market that is too empty is filled up to \(\bar y(s,\lambda)\); in between, nobody moves.
It is worth pausing on an apparent inconsistency between (118.6) and (118.2), because it is the place where a reader is most likely to suspect an error.
The Bellman equation evaluates the continuation at the unchanged workforce \(y\), while the transition law moves the workforce somewhere else.
Both are right, and the reason is that the \(\max\) and the \(\min\) have already dealt with the two cases in which the workforce moves: where arrivals come, the \(\min\) replaces the continuation by \(\lambda\), which is exactly what a market filled to \(\bar y\) is worth to anyone in it, and where workers leave, the \(\max\) replaces the whole expression by \(\lambda\).
The continuation at the unchanged \(y\) is therefore used only in the region where the workforce really is unchanged.
Note
The paper lets arrivals be random: a market short of workers receives \(a(s,y,\lambda)\,x\) of them, where \(x\) is a positive random variable with mean one, so that search “eliminates rents on average” rather than exactly.
Like the numerical examples in the paper’s appendix, we set \(x \equiv 1\), which gives (118.6).
118.5. A computable version#
We follow the appendix of Lucas and Prescott [1974]: a finite number of demand states, an integer workforce, and value function iteration on (118.2).
For the demand process we use the example in the paper’s own footnote: \(\log s\) follows an AR(1), discretized with the method of Tauchen.
For \(R\) we take a marginal revenue schedule that falls linearly in employment and reaches zero at a capacity \(N\),
which is the shape of the schedules drawn in the top panels of the paper’s Figure 5.
The capacity matters for more than convenience.
Lucas and Prescott require that employment stay bounded as demand grows without bound, and a schedule that never reaches zero violates that: markets would absorb unlimited numbers of workers in good states, and the answers would depend on where we truncated the grid rather than on the economics.
We will see below that this assumption is not a technicality.
The shape of \(R\) does something else that is easy to miss and that Exercise 118.5 takes up.
It sets how far employment moves when demand moves, and therefore how much there is to gain from sending a worker from one market to another.
Model = namedtuple('Model', ['P', 's', 'y', 'R', 'β'])

def create_model(n_s=7, ρ=0.9, sd=0.26, β=0.9, N=200, y_max=260):
    """An island economy.

    ρ and sd are the persistence and the stationary standard deviation of
    log demand, so that changing ρ alone does not change how variable
    demand is.  N is a market's capacity: marginal revenue reaches zero there.
    """
    mc = qe.markov.tauchen(n_s, ρ, sd*np.sqrt(1 - ρ**2))
    s = np.exp(mc.state_values)
    y = np.arange(y_max + 1)
    R = np.maximum(s[:, None]*(1 - y[None, :]/N), 0.0)
    R[:, 0] = 0.0
    return Model(P=mc.P, s=s, y=y, R=R, β=β)

model = create_model()
print("demand states:", model.s.round(3))
demand states: [0.458 0.595 0.771 1. 1.297 1.682 2.181]
The Bellman operator is (118.2) with the integral replaced by a sum.
We need some value of search to solve it, so we use \(\lambda = 7.1\) here, a number that Economy-wide equilibrium will turn out to have chosen for a reason.
def worker_value(model, λ, tol=1e-11, max_iter=10_000):
    "Solve the worker's functional equation by successive approximations."
    P, R, β = model.P, model.R, model.β
    v = np.full(R.shape, λ)
    for i in range(max_iter):
        v_new = np.maximum(λ, R + np.minimum(λ, β*(P @ v)))
        v_new[:, 0] = λ                     # an empty market holds no workers
        if np.max(np.abs(v_new - v)) < tol:
            return v_new, i
        v = v_new
    return v, max_iter

v, iters = worker_value(model, 7.1)
print(f"converged in {iters} iterations")
converged in 107 iterations
The two thresholds are the largest employment, and the largest workforce, at which the relevant value still covers \(\lambda\).
def thresholds(model, v, λ):
    "The employment threshold n̄(s) and the arrival threshold ȳ(s)."
    P, R, β = model.P, model.R, model.β
    EV = β*(P @ v)              # the continuation value at an unchanged workforce
    H = R + EV                  # the value of staying on as the marginal worker
    last = lambda A: np.array([np.max(np.where(A[i] >= λ)[0]) if (A[i, 1:] >= λ).any()
                               else 0 for i in range(len(model.s))])
    n_bar = last(H)
    y_bar = last(EV)            # ≤ n_bar automatically, because R ≥ 0
    return n_bar, y_bar

n_bar, y_bar = thresholds(model, v, 7.1)
print("n̄(s) =", n_bar)
print("ȳ(s) =", y_bar)
n̄(s) = [  0   5  41  71  97 118 134]
ȳ(s) = [  0   0   0  32  63  88 107]
Employment is capped by \(\bar n\), arrivals fill up to \(\bar y\), and (118.6) moves the workforce.
def stationary_distribution(model, n_bar, y_bar, tol=1e-14, max_iter=100_000):
    "The invariant distribution of the Markov chain on (s, y)."
    P, y = model.P, model.y
    n_s, n_y = len(model.s), len(y)
    ψ = np.ones((n_s, n_y))/(n_s*n_y)
    y_next = np.clip(y[None, :], y_bar[:, None], n_bar[:, None])
    for _ in range(max_iter):
        moved = np.array([np.bincount(y_next[i], weights=ψ[i], minlength=n_y)
                          for i in range(n_s)])
        ψ_new = P.T @ moved
        if np.max(np.abs(ψ_new - ψ)) < tol:
            return ψ_new
        ψ = ψ_new
    return ψ

def market_outcomes(model, λ):
    "Everything about a market at a given value of search."
    v, _ = worker_value(model, λ)
    n_bar, y_bar = thresholds(model, v, λ)
    ψ = stationary_distribution(model, n_bar, y_bar)
    y = model.y
    employment = np.minimum(y[None, :], n_bar[:, None])
    unemployment = y[None, :] - employment
    wage = np.take_along_axis(model.R, np.maximum(employment, 1), axis=1)
    total = (ψ*employment).sum()
    return dict(v=v, n_bar=n_bar, y_bar=y_bar, ψ=ψ,
                workforce=(ψ*y).sum(),
                employment=total,
                unemployment=(ψ*unemployment).sum(),
                # the mean wage per employed worker; empty markets get no weight
                wage=(ψ*employment*wage).sum()/total if total > 0 else np.nan)

out = market_outcomes(model, 7.1)
print(f"workforce {out['workforce']:.2f}, employment {out['employment']:.2f}, "
      f"unemployment {out['unemployment']:.2f}")
workforce 50.49, employment 49.16, unemployment 1.33
118.5.1. What a market looks like#
The thresholds describe the whole of a market’s behavior, so it is worth seeing them.
fig, axes = plt.subplots(1, 2, figsize=(11, 4))

axes[0].plot(model.s, out['n_bar'], 'o-', lw=2, label=r'$\bar n(s)$: employment')
axes[0].plot(model.s, out['y_bar'], 's--', lw=2, label=r'$\bar y(s)$: arrivals fill to')
axes[0].set_xlabel('demand state $s$')
axes[0].set_ylabel('workers')
axes[0].legend()

employs = out['n_bar'] > 0                # a state with n̄(s) = 0 employs nobody
wage_at_nbar = model.R[np.arange(len(model.s)), out['n_bar']]
axes[1].plot(out['n_bar'][employs], wage_at_nbar[employs], 'o-', lw=2)
axes[1].set_xlabel(r'employment $\bar n(s)$')
axes[1].set_ylabel('wage')
plt.tight_layout()
plt.show()
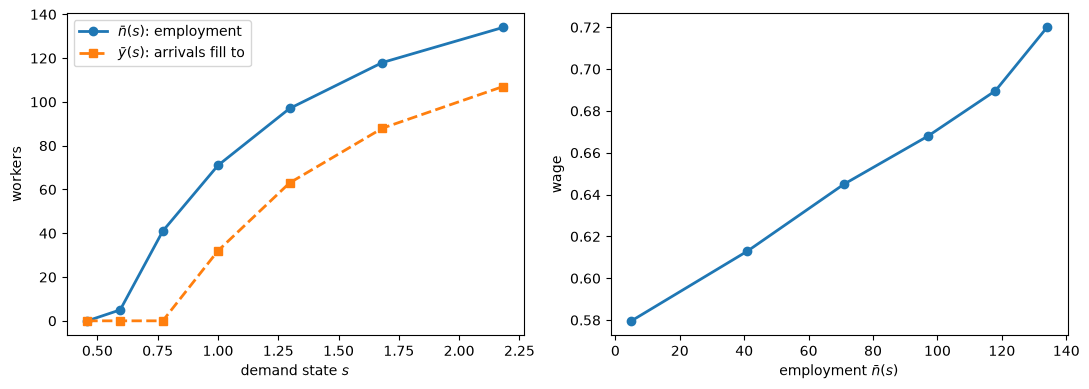
Fig. 118.1 The two thresholds, and the locus of employment and wages as demand shifts#
The right panel is the curve that Lucas and Prescott call \(SS\), the pairs of employment and wages that a market would trace out as demand shifted if its workforce never constrained it.
It leaves out the worst demand states, where \(\bar n(s) = 0\), because a market there employs nobody and pays no wage.
The curve is not flat.
A flat \(SS\) would mean that workers had a single reservation wage, accepting work above it and searching below it, which is what the partial-equilibrium search models of Job Search I: The McCall Search Model derive: there a reservation wage is the conclusion, and here it fails.
The reason is instructive: a change in demand moves the current wage, but it also carries information about future wages, and it changes the workforce that the market will carry into the future.
Those effects pull in opposite directions, so the locus can slope either way; in this calibration it happens to slope upward throughout.
118.5.2. The workforce distribution and a sample path#
Because arrivals are deterministic, the workforce moves between a small number of values, each one a threshold of some demand state.
fig, axes = plt.subplots(1, 2, figsize=(12, 4))

marginal = out['ψ'].sum(axis=0)
support = marginal > 1e-10
axes[0].stem(model.y[support], marginal[support], basefmt=' ')
axes[0].set_xlabel('workforce $y$')
axes[0].set_ylabel('probability')

mc = qe.MarkovChain(model.P)
idx = mc.simulate_indices(60, init=3, random_state=0)
path_y = np.empty(60, dtype=int)
path_y[0] = out['n_bar'][idx[0]]
for t in range(59):
    path_y[t+1] = np.clip(path_y[t], out['y_bar'][idx[t]], out['n_bar'][idx[t]])
path_n = np.minimum(path_y, out['n_bar'][idx])

axes[1].plot(path_y, lw=2, label='workforce')
axes[1].plot(path_n, lw=2, ls='--', label='employment')
axes[1].fill_between(range(60), path_n, path_y, alpha=0.3, label='unemployed')
axes[1].set_xlabel('period')
axes[1].set_ylabel('workers')
axes[1].legend()
plt.tight_layout()
plt.show()
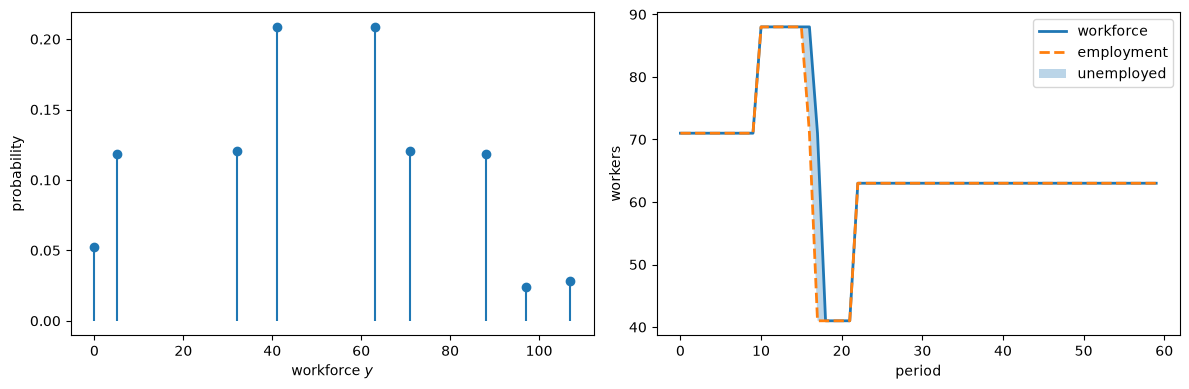
Fig. 118.2 The invariant distribution of the workforce, and one market over sixty periods#
The right panel shows the mechanism of the model in one picture.
A market is at rest whenever demand does not move.
When demand falls, the gap between the two lines opens for exactly one period: that period’s leavers are the unemployed, and by the next period they are somewhere else.
118.6. Economy-wide equilibrium#
So far \(\lambda\) has been a parameter.
Now close the model.
The economy has a fixed workforce, \(\mu\) per market.
For any \(\lambda\), the calculation above delivers the workforce that a market holds on average, and summing across markets gives the economy’s demand for workforce,
A higher \(\lambda\) makes every market shed workers sooner and fill up less, so \(E(y;\lambda)\) is decreasing.
Equilibrium is the \(\lambda^*\) at which markets want to hold exactly the workers the economy has:
Because the schedule is decreasing, bisection finds \(\lambda^*\).
def workforce_demand(model, λ):
    "The average workforce per market at the value of search λ."
    return market_outcomes(model, λ)['workforce']

def equilibrium_λ(model, μ, lo=0.3, hi=40.0, tol=1e-4):
    "Bisect on the decreasing demand schedule E(y; λ) = μ."
    while hi - lo > tol:
        mid = 0.5*(lo + hi)
        if workforce_demand(model, mid) > μ:
            lo = mid
        else:
            hi = mid
    return 0.5*(lo + hi)

μ = 50                        # workers per market, against a capacity of 200
λ_star = equilibrium_λ(model, μ)
eq = market_outcomes(model, λ_star)

print(f"equilibrium value of search  λ* = {λ_star:.3f}")
print(f"workforce per market            = {eq['workforce']:.2f}   (target {μ})")
print(f"employment per market           = {eq['employment']:.2f}")
print(f"unemployment per market         = {eq['unemployment']:.2f}")
print(f"unemployment rate               = {100*eq['unemployment']/eq['workforce']:.2f}%")
print(f"separation rate                 = "
      f"{100*eq['unemployment']/eq['employment']:.2f}% of the employed per period")
print(f"mean wage                       = {eq['wage']:.3f}")
equilibrium value of search  λ* = 7.121
workforce per market            = 50.00   (target 50)
employment per market           = 48.66
unemployment per market         = 1.34
unemployment rate               = 2.68%
separation rate                 = 2.75% of the employed per period
mean wage                       = 0.780
Lucas and Prescott draw this as a demand curve meeting a vertical supply curve, which is exactly what it is.
grid = np.linspace(0.6, 15.0, 45)
demand = np.array([market_outcomes(model, λ) for λ in grid])
E_y = np.array([d['workforce'] for d in demand])
E_u = np.array([d['unemployment'] for d in demand])

fig, axes = plt.subplots(1, 2, figsize=(11, 4))

axes[0].plot(E_y, grid, lw=2, label=r'demand $E(y;\lambda)$')
axes[0].axvline(μ, color='C1', lw=2, ls='--', label=r'supply $\mu$')
axes[0].plot(eq['workforce'], λ_star, 'ko', ms=8)
axes[0].set_xlabel('workforce per market')
axes[0].set_ylabel(r'value of search $\lambda$')
axes[0].legend()

axes[1].plot(E_y, E_u, lw=2)
axes[1].plot(eq['workforce'], eq['unemployment'], 'ko', ms=8)
axes[1].set_xlabel('workforce per market')
axes[1].set_ylabel('unemployment per market')
plt.tight_layout()
plt.show()
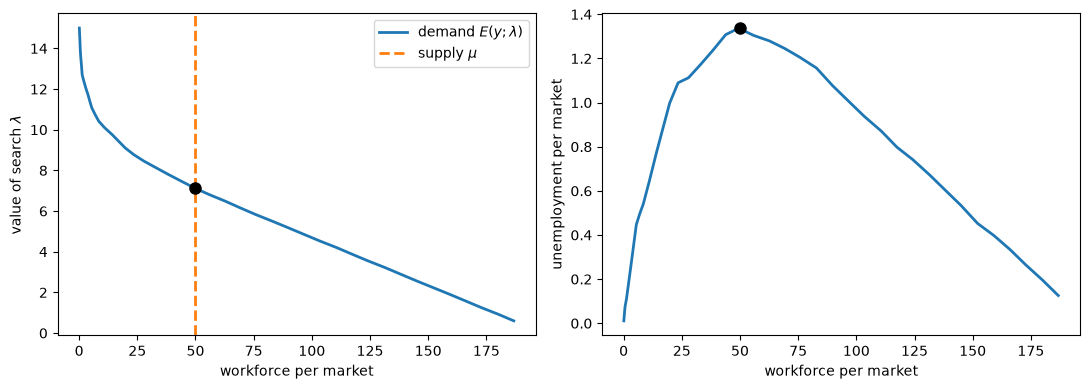
Fig. 118.3 The market for workers, and unemployment along the demand curve#
The left panel is the paper’s Figure 4.
The right panel corresponds to the bottom panels of the paper’s Figure 5, which plot average unemployment against \(\lambda\) for two numerical examples; since \(E(y;\lambda)\) is decreasing, plotting it against the workforce instead shows the same shape.
The right panel is the more interesting of the two, because unemployment is not monotone in the size of the workforce, a feature that Lucas and Prescott report from their own examples.
Where workers are scarce, \(\lambda\) is high, every market employs all it has, and almost nobody is ever shed.
Where workers are abundant, \(\lambda\) is low, every market is pressed against its capacity, and the two thresholds are squeezed together there, so even a large shift in demand moves few workers.
Unemployment is largest in between, and this is where the bounded capacity earns its keep: with a marginal revenue schedule that never reached zero, the thresholds would keep rising as \(\lambda\) fell, unemployment would rise without bound, and the right panel would have no peak at all.
118.6.1. Would anyone find it?#
Lucas and Prescott devote a section of the paper to a question that the equilibrium itself does not answer: we have assumed that workers know \(\lambda\), and said nothing about how they would come to know it.
Their answer is an adaptive story.
Suppose workers believe the value of search is higher than it is.
Then more of them leave their markets than can be placed at that return, so searchers and stayers alike are disappointed in the wages they expected, and they revise the number down.
Writing \(g\) for a decreasing function that vanishes at zero,
and since the demand schedule slopes down, the equilibrium is stable under this revision.
Note
That story and the algorithm we just ran rest on the same fact.
equilibrium_λ bisects on a decreasing schedule: when the candidate \(\lambda\) is too high, markets want fewer workers than the economy has, and the candidate comes down.
Bisection brackets the root rather than following the paper’s adjustment \(d\lambda/dt = g(\lambda - \lambda^*)\), but both work for the same reason: \(E(y;\lambda)\) is decreasing in \(\lambda\).
Lucas and Prescott are careful to add that this kind of stability “can have no relevance to the dynamic response to regularly recurring shocks”, which is the distinction between learning an equilibrium and responding within one.
118.6.2. Where markets sit#
The three regions of (118.6) are a partition of the state space, so the invariant distribution says how much of the economy is in each.
y2 = model.y[None, :]
sheds = y2 > eq['n_bar'][:, None]                       # region I: workers leave
fills = y2 < eq['y_bar'][:, None]                       # region III: workers arrive
still = ~sheds & ~fills                                 # region II: nobody moves

for name, region in (('shedding workers', sheds), ('receiving workers', fills),
                     ('neither', still)):
    print(f"{name:>20}: {100*eq['ψ'][region].sum():5.1f}% of markets")
print(f"{'with no workers':>20}: {100*eq['ψ'][:, 0].sum():5.1f}% of markets")
    shedding workers:   5.6% of markets
   receiving workers:   5.2% of markets
             neither:  89.2% of markets
     with no workers:   5.2% of markets
Nearly nine markets in ten are completely still in any given period.
All of the economy’s unemployment comes from the one in twenty that is contracting, and an equal number of markets is taking those workers in.
The last line is the extreme case of a contracting market, and it is visible in the thresholds printed earlier as the leading zeros of \(\bar n(s)\) and \(\bar y(s)\): in the worst demand states a market employs nobody and attracts nobody.
Those markets close, and they stay closed until they draw a state good enough to be worth entering again.
118.6.3. The wage distribution#
We can now answer the question the Overview began with.
The search literature hands its worker a distribution of wage offers and asks what he should do with it.
Here that distribution is an output: every market pays the marginal product of labor in it, and what a market pays depends on the demand it drew and on how many workers chose to be there.
employed = np.minimum(model.y[None, :], eq['n_bar'][:, None])
wage = np.take_along_axis(model.R, np.maximum(employed, 1), axis=1)
weight = eq['ψ']*employed                  # weight a market by the workers in it
weight = weight/weight.sum()

w, p = wage.ravel(), weight.ravel()
order = np.argsort(w)
w, p = w[order], p[order]
cdf = np.cumsum(p)
quantile = lambda a: w[np.searchsorted(cdf, a)]
mean = (w*p).sum()

fig, ax = plt.subplots(figsize=(7.5, 4))
ax.hist(w, bins=30, weights=p, color='C0', alpha=0.85)
ax.axvline(mean, color='k', lw=1.5, label=f'mean {mean:.3f}')
ax.axvline(λ_star*(1 - model.β), color='C1', lw=1.5, ls='--',
           label=f'flow value of search {λ_star*(1-model.β):.3f}')
ax.set_xlabel('wage')
ax.set_ylabel('share of workers')
ax.set_xlim(0.5, 1.45)            # a thin tail runs past this; see the print below
ax.legend()
plt.tight_layout()
plt.show()

print(f"mean {mean:.3f}, "
      f"p10 {quantile(0.1):.3f}, median {quantile(0.5):.3f}, p90 {quantile(0.9):.3f}")
print(f"p90/p10 = {quantile(0.9)/quantile(0.1):.2f},  "
      f"highest wage paid {w[p > 1e-12].max():.3f}")
print(f"share paid less than the flow value of search: "
      f"{100*p[w < λ_star*(1 - model.β)].sum():.0f}%")
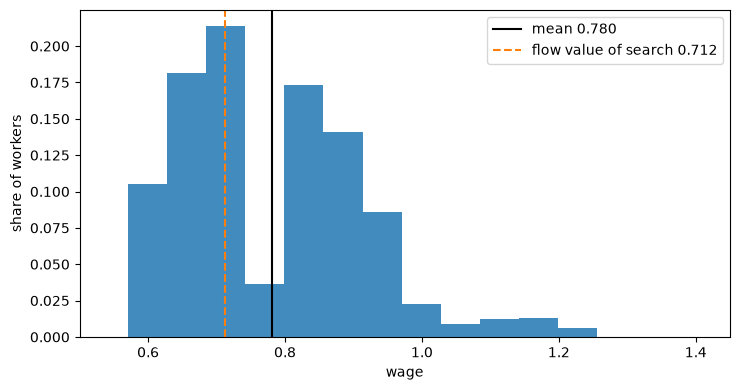
Fig. 118.4 Wages across identical workers, at the equilibrium#
mean 0.780, p10 0.617, median 0.733, p90 0.950
p90/p10 = 1.54,  highest wage paid 1.832
share paid less than the flow value of search: 40%
Workers in this economy are identical.
They have the same skills, the same preferences and the same information, and they are free to leave at any time.
They are nevertheless paid differently, by half as much again at the ninetieth percentile as at the tenth, and the dispersion is not a friction or a mistake: it is what equalizes the value of being in one market or another when demand has moved markets apart and it takes a period to cross between them.
The dashed line is the flow value of search, \((1-\beta)\lambda^*\), which is what a searcher’s position is worth per period.
Two fifths of workers are paid less than that, and stay.
There is no puzzle in it, but there is something worth seeing: what a worker holds is not his current wage.
It is a position in a particular market, which carries a claim on that market’s future and the option to walk away later, and a market can be worth being in today precisely because it is depressed today and will not be for long.
Note
Notice what this model does not contain.
There is no matching function, no bargaining, and no wage rigidity.
Unemployment is here because moving takes a period, and in equilibrium somebody is always moving.
118.7. Relation to other lectures#
Baley et al. [2023] open by observing that there is no standard model of frictional unemployment, but three workable classes of them: matching models in the Diamond-Mortensen-Pissarides tradition, equilibrium versions of McCall [1970], and search-island models in the tradition of Lucas and Prescott [1974].
Calibrated versions of all three fit data on labor market flows and deliver plausible responses of unemployment to policies like unemployment insurance and layoff taxes.
This lecture is the third class, and the McCall lectures in this series are the second.
It is worth being explicit about what this model supplies that the search lectures elsewhere in this series take as given.
Job Search I: The McCall Search Model and its sequels study a worker who draws from a known wage offer distribution and chooses a reservation wage.
That worker’s problem is a piece of this one: here too a worker compares what a market offers him with the value of looking elsewhere.
What is added is everything on the other side of the offer.
The wage a worker is offered is the marginal product of labor in a market whose workforce was determined by where other workers decided to go, and the value of looking elsewhere, \(\lambda\), is the number that clears the economy-wide market for workers.
Two consequences are worth noting.
The first is that there is no reservation wage, and the reason runs deeper than a comparison of numbers.
At the equilibrium computed above, workers stay on, and nobody leaves, in markets paying as little as \(0.583\), while elsewhere workers walk away from markets paying \(0.674\), so no cutoff between the two sorts the markets a worker accepts from those he leaves.
But the leavers are not turning down an offer of \(0.674\) in favor of something better, and nobody turns them away from it.
At \(\bar n(s)\) every worker in the market, stayer or leaver, gets exactly \(\lambda\).
The leavers could stay, but then employment would be the whole workforce \(y\), the wage would fall to \(R(s, y)\), and staying would be worth less than \(\lambda\).
So no offer is rejected against a cutoff wage, and nobody is denied a job at the going wage.
The margin is the market’s level of employment, and leaving is a choice made at a point where staying and leaving are worth the same.
The second is about the flow rates between employment and unemployment, and it is worth setting out as a ladder.
A Lake Model of Employment and Unemployment takes both rates as parameters: a job finding rate of \(0.283\) and a separation rate of \(0.013\) go in, and the unemployment rate comes out.
Lake Model with an Endogenous Job Finding Rate climbs one rung, making the job finding rate the outcome of a McCall problem, though still against a wage distribution that is given.
This lecture is the next rung: both rates are equilibrium objects.
The separation rate printed above, around \(2.7\) percent of the employed per period, is nothing but the frequency with which demand shifts carry markets below their employment thresholds.
Warning
The job finding rate in this model is one.
A worker who leaves is placed in some market at the start of the next period, always, so every spell of unemployment lasts exactly one period and the model has nothing to say about unemployment duration.
That is a direct consequence of directed search, and it is the first thing Alvarez and Veracierto [1999] give up: when searchers arrive uniformly, a worker can land in a market that is itself shedding workers and have to move again.
Duration becomes an equilibrium object there, and averages \(2.4\) periods in their calibration.
The connection to Investment Under Uncertainty is methodological, and close.
In the 1971 paper a competitive industry’s capital stock is a Markov process whose invariant distribution describes the long run, and the equilibrium is computed by solving a fixed point problem in a function.
Here a market’s workforce is a Markov process whose invariant distribution describes the long run, and the equilibrium is computed by solving a fixed point problem in a function and then one more, in the single number \(\lambda\).
The same authors wrote both papers within three years, and the second is the first one’s method turned on a question about labor.
118.7.1. What the island model became#
Alvarez and Veracierto [1999] took this model and made it a tool for quantitative policy analysis, in their words by “modifying Lucas and Prescott’s (1974) island model to incorporate undirected search and out-of-the-labor-force participation”.
Four things change.
Search becomes undirected: searchers “arrive uniformly across all islands”, so an island’s workforce next period is its own employment plus the same inflow every other island gets, whether it wants the workers or not.
The nonemployed gain a second option, home production, so that labor force participation is a margin and the model has three states rather than two.
Islands produce with a decreasing returns technology subject to persistent productivity shocks rather than facing a shifting demand curve.
And agents trade a complete set of state-contingent securities, which the authors justify by their own earlier finding that the insurance role of the policies they study is quantitatively small.
With that machinery they evaluate minimum wages, two models of unions, firing taxes and unemployment insurance, at a model period of six weeks.
Note
The first of those changes is worth dwelling on, because it shows what directed search is doing here.
In this lecture \(\lambda\) is a price: raise it and every market sheds workers sooner and fills up less, so the workforce that markets want to hold falls, and (118.8) pins \(\lambda\) down exactly as a market-clearing condition pins down any other price.
Behind that is the \(\min\) in (118.2): because searchers go only where it pays them to go, every market that receives workers is worth exactly \(\lambda\) to them, and \(\lambda\) needs no condition of its own.
Under undirected search that link is broken.
A searcher lands in a market drawn at random, so \(\lambda\) must equal the discounted value of landing in a randomly drawn market, and the common inflow \(U\) becomes a second unknown.
With a fixed population there are still two conditions for these two unknowns, the population and the consistency of \(\lambda\), so the level of the workforce is not left free.
What is lost is the simple structure: the consistency condition need not be monotone in \(\lambda\), and nothing guarantees a unique equilibrium.
Exercise 118.4 works through both points.
Alvarez and Veracierto add the participation margin for a different reason.
The policies they study act on whether people look for work at all, as well as on firms’ hiring and firing and on workers’ search, and with home production the inflow of searchers is set by the indifference between searching and staying home, so that the size of the labor force becomes an outcome.
118.7.2. Returns to labor mobility#
Baley et al. [2025] and Baley et al. [2023] argue that models of this family live or die by one quantity, which they call the returns to labor mobility: how much more a worker produces where he is going than where he is.
It is the quantity that decides what a layoff tax does to unemployment, and whether skill losses at the time of a quit can reverse the effect of turbulence on unemployment.
And it is not a property of the shock alone.
It is a property of the shock and of the technology that intermediates it, which is why the two papers insist on calibrating productivity processes against evidence on firm size dynamics rather than on per-worker productivity statistics alone.
The sharpest way to see this is to compare our two-state economy of Exercise 118.3 with Alvarez and Veracierto [2001], whose calibration Baley et al. [2025] take from establishment data on job creation and destruction.
The two economies face almost the same shock: ours doubles demand between the low and the high state, theirs has a productivity ratio of \(2.12\).
What the shock does to employment could hardly be more different.
In our two-state economy mean employment is about 2.6 times larger in the high state than in the low one, as Exercise 118.5 computes.
In theirs, Baley et al. [2025] compute from Alvarez and Veracierto’s parameters that a low-productivity establishment employs only \(3.81\) percent as many workers as a high-productivity one, a ratio of about 26, and that high-productivity establishments hold more than \(96\) percent of all employment.
Most of the gap is the technology.
In Alvarez and Veracierto an establishment produces \(x k^{\xi} n^{\psi}\) with \(\xi + \psi < 1\), and equating marginal products across establishments gives
so a shock is amplified by an exponent that explodes as returns to scale approach one.
With their parameters the exponent is about \(4.3\), which turns a productivity ratio of \(2.12\) into an employment ratio of about \(26\).
That is a frictionless benchmark: it equates marginal products across establishments, as instantaneous and costless reallocation would.
Our marginal revenue schedule, which falls linearly to zero at a capacity, amplifies a doubling of demand about as much as a decreasing returns technology whose labor exponent is a little above one half.
Exercise 118.5 puts (118.9) into this model and shows what it does to unemployment.
118.8. Exercises#
Exercise 118.1
Lucas and Prescott [1974] report two comparative statics from their own numerical examples:
Overall, we found for low and high persistence in demand that unemployment rates were low. In the former case, there was little gained by reallocating workers, while in the latter reallocation occurred infrequently. As expected, the greater the variability of demand, holding the degree of persistence fixed, the greater the level of unemployment.
Check both in this calibration.
Compute the equilibrium unemployment rate for persistence \(\rho \in \{0, 0.3, 0.6, 0.8, 0.9, 0.95, 0.99\}\), holding the stationary standard deviation of \(\log s\) fixed at \(0.26\) and \(\mu\) at \(50\). Is the relationship monotone?
Compute it for stationary standard deviations \(\{0.10, 0.18, 0.26, 0.34, 0.45\}\), holding \(\rho = 0.9\).
Explain the shape you find in part 1.
The two parameters you are varying are the same two that Job Search VI: Persistent and Transitory Wage Shocks varies, there as the persistence and volatility of a worker’s wage offers rather than of his market’s demand.
The difference is what the experiment delivers: a reservation wage there, an unemployment rate here.
Solution
Holding the stationary standard deviation fixed as \(\rho\) varies is what the argument sd of create_model already does, so each experiment is one call.
print(f"{'ρ':>8}{'λ*':>9}{'workforce':>12}{'u rate':>10}")
u_by_ρ = []
for ρ in (0.0, 0.3, 0.6, 0.8, 0.9, 0.95, 0.99):
    m_ρ = create_model(ρ=ρ)
    λ_ρ = equilibrium_λ(m_ρ, μ)
    r = market_outcomes(m_ρ, λ_ρ)
    u_by_ρ.append(100*r['unemployment']/r['workforce'])
    print(f"{ρ:>8}{λ_ρ:>9.3f}{r['workforce']:>12.1f}{u_by_ρ[-1]:>9.2f}%")
       ρ       λ*   workforce    u rate
     0.0    7.247        49.7     0.00%
     0.3    7.153        50.4     0.02%
     0.6    7.230        50.2     1.21%
     0.8    7.186        50.1     2.54%
     0.9    7.121        50.0     2.68%
    0.95    7.108        50.1     1.60%
    0.99    7.065        50.0     0.01%
The second experiment varies how far demand moves, holding how long it stays.
print(f"{'sd':>8}{'λ*':>9}{'workforce':>12}{'u rate':>10}")
for sd in (0.10, 0.18, 0.26, 0.34, 0.45):
    m_sd = create_model(sd=sd)
    λ_sd = equilibrium_λ(m_sd, μ)
    r = market_outcomes(m_sd, λ_sd)
    print(f"{sd:>8}{λ_sd:>9.3f}{r['workforce']:>12.1f}"
          f"{100*r['unemployment']/r['workforce']:>9.2f}%")
      sd       λ*   workforce    u rate
     0.1    7.092        49.9     0.37%
    0.18    7.099        50.1     1.45%
    0.26    7.121        50.0     2.68%
    0.34    7.292        49.9     3.40%
    0.45    7.537        50.0     4.97%
Variability does what one expects: demand that moves further moves more workers, and the unemployment rate rises steadily with it.
Persistence does not.
The unemployment rate is near zero at both ends and reaches its maximum in between, which is the shape Lucas and Prescott describe.
The two ends are near zero for opposite reasons.
When demand is nearly independent across periods, a market that is unlucky today expects to be average tomorrow, so its workers see little point in moving: the thresholds \(\bar n\) and \(\bar y\) are close together and almost nobody is ever shed.
When demand is nearly permanent, the thresholds are far apart, but a market almost never crosses from one to the other, so the reallocation that would make workers move hardly ever happens.
Unemployment needs demand shifts that are both worth responding to and frequent, which is a combination that only intermediate persistence delivers.
Exercise 118.2
In their concluding section, Lucas and Prescott consider a lump-sum cost \(c\) of leaving a market to search, so that the right side of (118.3) becomes \(\lambda - c\) rather than \(\lambda\): a worker who leaves collects the value of search net of what it costs him to get there.
The arrival condition (118.5) is unchanged, since it prices the market for workers who are already searching.
They report that the cost lowers unemployment, and remark that this
shows that lower average unemployment is not, in general, associated with higher welfare for workers.
Modify the code to allow a cost \(c\), and for \(c \in \{0, 0.2, 0.5, 1, 2\}\) report the equilibrium \(\lambda^*\), the unemployment rate, the expected value of a worker under the invariant distribution, which weights each market by the workers in it,
and output per market,
which is the area under the marginal revenue schedule up to employment.
Does lower unemployment mean better off?
Solution
Only two lines change: the outside option inside the max of (118.2), and the threshold that defines \(\bar n\).
def worker_value_cost(model, λ, c, tol=1e-11, max_iter=10_000):
    "The worker's problem when leaving costs c."
    P, R, β = model.P, model.R, model.β
    v = np.full(R.shape, λ - c)
    for _ in range(max_iter):
        v_new = np.maximum(λ - c, R + np.minimum(λ, β*(P @ v)))
        v_new[:, 0] = λ - c
        if np.max(np.abs(v_new - v)) < tol:
            return v_new
        v = v_new
    return v

def outcomes_cost(model, λ, c):
    v = worker_value_cost(model, λ, c)
    P, R, β, y = model.P, model.R, model.β, model.y
    EV = β*(P @ v)
    H = R + EV
    last = lambda A, bar: np.array([np.max(np.where(A[i] >= bar)[0])
                                    if (A[i, 1:] >= bar).any() else 0
                                    for i in range(len(model.s))])
    n_bar = last(H, λ - c)      # staying is worth λ - c to the leaver
    y_bar = last(EV, λ)         # arrivals are priced at λ; still ≤ n_bar
    ψ = stationary_distribution(model, n_bar, y_bar)
    employment = np.minimum(y[None, :], n_bar[:, None])
    output = np.take_along_axis(np.cumsum(R, axis=1), employment, axis=1)
    return dict(workforce=(ψ*y).sum(),
                unemployment=(ψ*(y[None, :] - employment)).sum(),
                welfare=(ψ*y*v).sum()/(ψ*y).sum(),   # per worker, not per market
                output=(ψ*output).sum())

def equilibrium_λ_cost(model, μ, c, lo=0.3, hi=40.0, tol=1e-4):
    while hi - lo > tol:
        mid = 0.5*(lo + hi)
        if outcomes_cost(model, mid, c)['workforce'] > μ:
            lo = mid
        else:
            hi = mid
    return 0.5*(lo + hi)
Now sweep the cost.
print(f"{'c':>6}{'λ*':>9}{'λ*-c':>9}{'u rate':>9}{'E[v]':>9}{'output':>9}")
for c in (0.0, 0.2, 0.5, 1.0, 2.0):
    λ_c = equilibrium_λ_cost(model, μ, c)
    r = outcomes_cost(model, λ_c, c)
    print(f"{c:>6}{λ_c:>9.3f}{λ_c - c:>9.3f}"
          f"{100*r['unemployment']/r['workforce']:>8.2f}%{r['welfare']:>9.3f}"
          f"{r['output']:>9.3f}")
     c       λ*     λ*-c   u rate     E[v]   output
   0.0    7.121    7.121    2.68%    7.575   48.100
   0.2    7.227    7.027    2.24%    7.582   48.055
   0.5    7.403    6.903    1.58%    7.594   47.758
   1.0    7.681    6.681    1.14%    7.632   47.363
   2.0    8.290    6.290    0.50%    7.698   46.592
A cost of two cuts measured unemployment by more than four fifths, from \(2.7\) percent to \(0.5\) percent.
It also cuts output, by about three percent.
That is the paper’s point, and it is worth stating plainly: the unemployment that the cost eliminated was productive.
Those workers were not idle in any useful sense; they were in transit from markets where their marginal product had fallen to markets where it was high, and the cost keeps them where they are.
The rest of the table shows why “welfare” needs saying carefully.
The value of the option a worker holds, \(\lambda^* - c\), falls at every step: the outside option is worth less, which is what makes workers stay.
Yet the expected present value of a worker’s own earnings rises.
A worker’s income is the wage when he is employed and nothing when he is searching, and the cost buys him fewer periods of nothing.
What he gains that way, the economy loses more than twice over in output, because the match between workers and markets is worse.
So unemployment is not a welfare index, which is the lesson Lucas and Prescott draw, and in this calibration even the two welfare measures move in opposite directions.
It would be fair to suspect that so stark a result is an artifact of a model this stripped down.
It is not.
Alvarez and Veracierto [1999] run the same experiment as a firing tax inside a calibrated version of this economy, with taxes worth between three and twelve months of average wages.
At twelve months the tax takes the unemployment rate down from \(5.3\) to \(3.7\) percent and pushes the average duration of unemployment up from \(2.4\) to \(5.1\) periods.
When home and market goods are perfect substitutes it also cuts employment to \(86\) percent of its laissez-faire level, because so many fewer people search; with less substitutability employment falls much less, and with little enough it rises.
The number you have just computed has a use beyond the comparison.
Baley et al. [2023] make a diagnostic out of a closely related number: the minimum layoff tax that shuts down voluntary separations altogether.
Here even a cost of \(2\), which is about \(2.6\) times a period’s average wage, does not do that: it takes unemployment to a fifth of its laissez-faire rate, not to zero.
Their point is that this number has to be large to be credible, because extensive reallocation is observed in economies whose layoff costs differ enormously; a model in which a modest cost stops workers moving is a model whose returns to labor mobility are too low.
Exercise 118.5 asks what sets them.
Exercise 118.3
The numerical examples in the appendix of Lucas and Prescott [1974] use just two demand states, with
Build that economy, keeping \(R(s,n) = s\,(1 - n/N)^{+}\) from the lecture, with capacity \(N = 200\).
For \(\lambda\) on a grid, plot workforce demand and average unemployment against \(\lambda\), as in the bottom panels of the paper’s Figure 5.
Show that the invariant distribution puts all of its mass on two values of the workforce, and say which two.
Use that fact to derive a formula for average unemployment per market in terms of \(\bar n\), \(\bar y\) and the persistence \(\rho\), and check it against the computed value.
Solution
The two-state chain needs its own constructor, but everything else is reused.
def two_state_model(ρ=0.9, s_lo=1.0, s_hi=2.0, β=0.9, N=200, y_max=260):
    P = np.array([[ρ, 1-ρ], [1-ρ, ρ]])
    s = np.array([s_lo, s_hi])
    y = np.arange(y_max + 1)
    R = np.maximum(s[:, None]*(1 - y[None, :]/N), 0.0)
    R[:, 0] = 0.0
    return Model(P=P, s=s, y=y, R=R, β=β)

two = two_state_model()
grid2 = np.linspace(0.4, 14.0, 45)
res2 = [market_outcomes(two, λ) for λ in grid2]
Ey2 = np.array([r['workforce'] for r in res2])
Eu2 = np.array([r['unemployment'] for r in res2])
The paper puts \(\lambda\) on the vertical axis.
fig, axes = plt.subplots(1, 2, figsize=(10, 4.2))
axes[0].plot(Ey2, grid2, lw=2)
axes[0].set_xlabel('workforce demand per market')
axes[1].plot(Eu2, grid2, lw=2)
axes[1].set_xlabel('average unemployment per market')
for ax in axes:
    ax.set_ylabel(r'$\lambda$')
plt.tight_layout()
plt.show()
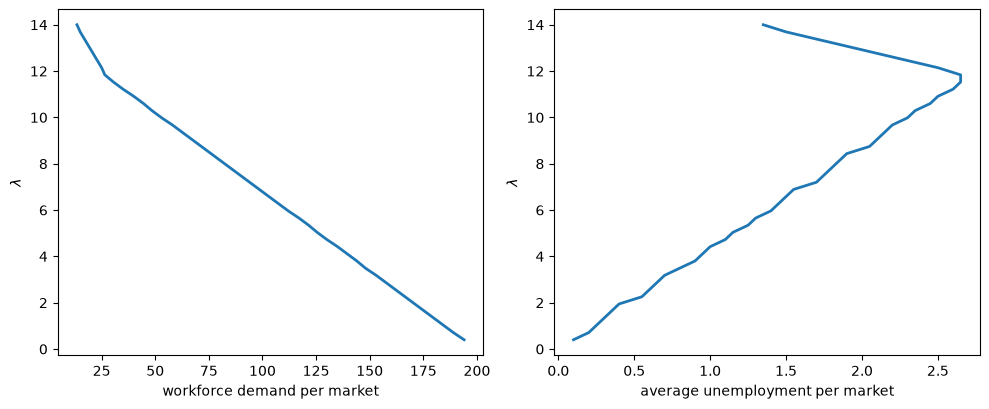
The right panel has the shape of the bottom panels of the paper’s Figure 5: average unemployment is largest at intermediate values of \(\lambda\).
For part 2, look at the support of the invariant distribution.
r2 = market_outcomes(two, 6.0)
support = np.where(r2['ψ'].sum(axis=0) > 1e-12)[0]
print("workforce values with positive probability:", support)
print("n̄(s) =", r2['n_bar'], "   ȳ(s) =", r2['y_bar'])
workforce values with positive probability: [ 98 125]
n̄(s) = [ 98 140]    ȳ(s) = [ 78 125]
The two values are \(\bar n(s_{\text{low}})\) and \(\bar y(s_{\text{high}})\).
To see why, follow (118.6).
In the low state the workforce is clipped into \([\bar y(s_{\text{low}}), \bar n(s_{\text{low}})]\) and in the high state into \([\bar y(s_{\text{high}}), \bar n(s_{\text{high}})]\), and with these parameters the second interval lies entirely above the first.
So one period in the low state carries any workforce to \(\bar n(s_{\text{low}})\), one period in the high state carries it to \(\bar y(s_{\text{high}})\), and the market shuttles between the two.
For part 3, unemployment is positive only in the first period of a downturn: the market enters with \(\bar y(s_{\text{high}})\) workers, demand has just fallen, and employment is \(\bar n(s_{\text{low}})\).
That event is “the state was high last period and is low now”, which has stationary probability \(\tfrac12 (1-\rho)\), so
predicted = 0.5*(1 - 0.9)*(r2['y_bar'][1] - r2['n_bar'][0])
print(f"formula:  {predicted:.4f}")
print(f"computed: {r2['unemployment']:.4f}")
formula:  1.3500
computed: 1.3500
The formula also explains the hump.
Average unemployment is the gap between two thresholds, multiplied by the chance of crossing it.
As \(\lambda\) falls, both thresholds rise, but not in step, and the gap between them widens and then narrows again.
Exercise 118.4
This exercise asks what the model’s directed search is doing.
Alvarez and Veracierto [1999] replace it with undirected search: a searcher cannot choose where to go, and every market receives the same inflow \(U\), which is the economy’s unemployment per market.
Show that under undirected search the \(\min\) disappears from (118.2), and say which economic condition it was enforcing.
Write down the transition law for a market’s workforce, and show that at any stationary distribution the inflow \(U\) equals the average outflow. Does the same identity hold under directed search?
Under directed search, (118.8) pins down \(\lambda\). Under undirected search, what condition must \(\lambda\) satisfy instead? Count the unknowns and the conditions of an equilibrium with a fixed workforce \(\mu\) per market.
Take the lecture’s seven-state calibration and an inflow of \(U = 1\), and then of \(U = 3\). For \(\lambda\) on a grid from \(3\) to \(10\), compute the gap between the value of search implied by \(\lambda\) and \(\lambda\) itself, and find the values of \(\lambda\) at which it vanishes. What does this say about equilibrium under undirected search?
Solution
For part 1, the \(\min\) in (118.2) is not a choice that anyone makes.
It is the restriction that the continuation value in a market cannot exceed \(\lambda\), which competition among searchers imposes: if some market promised more, searchers would go there until it no longer did.
Take away their ability to choose where to go and nothing enforces it.
A worker who stays simply collects the wage and the continuation value his own market happens to deliver,
and the continuation can be worth more or less than \(\lambda\), because nobody can act on the difference.
For part 2, employment is still \(n(s,y) = \min\{\bar n(s), y\}\), those not employed leave, and the inflow is the same everywhere, so
At a stationary distribution \(E[y'] = E[y]\), so averaging across markets gives
the inflow equals the average outflow.
That is an accounting identity, and it holds under directed search too.
At the stationary distribution of the lecture’s own transition law (118.6), the workers arriving in markets that fill up equal the workers leaving markets that shed, at every value of \(\lambda\) and not only at \(\lambda^*\).
y = model.y
print(f"{'λ':>8}{'E[y]':>9}{'outflow':>10}{'inflow':>9}")
for λ in (4.0, λ_star, 10.0):
    r = market_outcomes(model, λ)
    y_next = np.clip(y[None, :], r['y_bar'][:, None], r['n_bar'][:, None])
    outflow = (r['ψ']*np.maximum(y[None, :] - y_next, 0)).sum()
    inflow = (r['ψ']*np.maximum(y_next - y[None, :], 0)).sum()
    print(f"{λ:>8.3f}{r['workforce']:>9.2f}{outflow:>10.4f}{inflow:>9.4f}")
       λ     E[y]   outflow   inflow
   4.000   114.76    0.8259   0.8259
   7.121    50.00    1.3377   1.3377
  10.000    12.00    0.6825   0.6825
So the identity cannot be what distinguishes the two models.
What distinguishes them is how \(\lambda\) is determined.
For part 3, a searcher under undirected search lands in a market drawn at random from the invariant distribution, so the value of search must satisfy
the discounted value of landing in a randomly drawn market.
An equilibrium with a fixed population therefore has two unknowns, \(\lambda\) and \(U\), and two conditions, \(\mu = \sum_{s,y} \psi(s,y)\, y\) and the condition above.
The level of the workforce is not left free: a given \(\mu\) selects \(U\), and the consistency condition selects \(\lambda\).
The difference from directed search lies in how \(\lambda\) is pinned.
There the \(\min\) makes every market that receives workers worth exactly \(\lambda\), so \(\lambda\) needs no separate consistency condition, and \(\mu\) pins it down alone, through a schedule that slopes down.
Here \(\lambda\) needs a condition of its own, and nothing makes that condition monotone in \(\lambda\).
For part 4, a market under undirected search keeps the Bellman equation of part 1, with next period’s workforce \(n(s,y) + U\), and its employment threshold is the largest workforce at which staying is still worth \(\lambda\).
def undirected_market(model, λ, U, tol=1e-10, max_iter=20_000):
    "Every market receives U searchers each period, whether it wants them or not."
    P, R, β, y = model.P, model.R, model.β, model.y
    shift = np.minimum(y + U, y[-1])      # next workforce of a market that keeps everyone
    v = np.full(R.shape, λ)
    for _ in range(max_iter):
        v_new = np.maximum(λ, R + β*(P @ v)[:, shift])
        if np.max(np.abs(v_new - v)) < tol:
            break
        v = v_new
    v = v_new
    stay = R + β*(P @ v)[:, shift]
    n_bar = np.array([np.max(np.where(stay[i] >= λ)[0]) if (stay[i, 1:] >= λ).any()
                      else 0 for i in range(len(model.s))])
    # the invariant distribution of y' = min(y, n̄(s)) + U
    y_next = np.minimum(np.minimum(y[None, :], n_bar[:, None]) + U, y[-1])
    ψ = np.ones(R.shape)/R.size
    for _ in range(100_000):
        moved = np.array([np.bincount(y_next[i], weights=ψ[i], minlength=len(y))
                          for i in range(len(model.s))])
        ψ_new = P.T @ moved
        if np.max(np.abs(ψ_new - ψ)) < 1e-13:
            break
        ψ = ψ_new
    ψ = ψ_new
    return β*(ψ*v).sum(), (ψ*y).sum()     # the implied value of search, mean workforce
Now sweep \(\lambda\) for each inflow and look for the values at which the implied value of search equals \(\lambda\).
λ_grid = np.arange(3.0, 10.01, 0.25)
fig, ax = plt.subplots(figsize=(7, 4))
for U in (1, 3):
    implied, mean_y = np.array([undirected_market(model, λ, U) for λ in λ_grid]).T
    gap = implied - λ_grid
    ax.plot(λ_grid, gap, lw=2, label=f'$U = {U}$')
    crossings = np.where(np.diff(np.sign(gap)) != 0)[0]
    print(f"U = {U}: {len(crossings)} solution(s)")
    for i in crossings:
        w = gap[i]/(gap[i] - gap[i+1])                  # linear interpolation
        print(f"    λ ≈ {λ_grid[i] + w*(λ_grid[i+1] - λ_grid[i]):.2f},"
              f"  mean workforce ≈ {mean_y[i] + w*(mean_y[i+1] - mean_y[i]):.0f}")
ax.axhline(0, color='k', lw=0.8)
ax.set_xlabel(r'$\lambda$')
ax.set_ylabel(r'$\beta\, E[v] - \lambda$')
ax.legend()
plt.tight_layout()
plt.show()
U = 1: 2 solution(s)
    λ ≈ 4.76,  mean workforce ≈ 97
    λ ≈ 8.23,  mean workforce ≈ 26
U = 3: 0 solution(s)
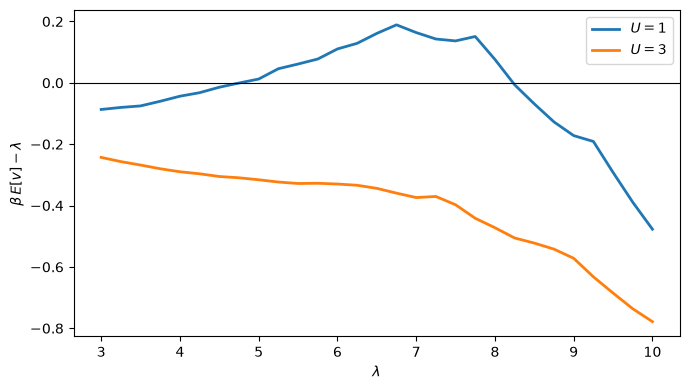
With \(U = 1\) the gap is negative at both ends of the grid and positive in between, so the consistency condition has two solutions, one with a crowded economy and a low value of search and one with a sparse economy and a high one.
With \(U = 3\) the gap is negative everywhere on the grid, and there is no solution at all.
So under undirected search the level of the workforce is still pinned down, but neither existence nor uniqueness comes for free, as they do under directed search, where Proposition 5 of Lucas and Prescott [1974] delivers a unique \(\lambda^*\) because \(E(y;\lambda)\) is decreasing.
The shape of the gap has a reading.
A searcher’s prospects come from markets whose demand has just improved and that a trickle of \(U\) arrivals per period has not yet filled.
When \(\lambda\) is low, the employment thresholds of all demand states are crowded together near capacity, so a change in demand opens little room; when \(\lambda\) is high, many markets close, and a searcher who lands in one has to move again.
The rents that make searching worthwhile are largest in between.
What Alvarez and Veracierto add is the participation margin: the nonemployed choose between searching and home production.
That replaces the fixed population with an indifference condition, the inflow of searchers adjusts until searching and staying home are equally good, and the size of the labor force becomes an outcome.
Their own reason for adding it is the policies they study, which act on participation as well as on firms’ employment decisions and on workers’ search.
Exercise 118.5
How far employment moves when demand moves is not a property of the demand process alone.
It also depends on the technology through which the shock reaches the labor market, and Baley et al. [2025] argue that this is the quantity a calibration most needs to get right.
Replace the marginal revenue schedule of this lecture with the one implied by a decreasing returns production function.
If a market produces \(s\, n^{a}\) with \(0 < a < 1\), the marginal product of labor is
where the shift \(n_0\) keeps it bounded at \(n = 0\).
Build the two-state economy of Exercise 118.3 with this schedule, for \(a \in \{0.4, 0.6, 0.75\}\), and solve each for its own equilibrium. Report mean employment in each demand state, the ratio of the two, and the unemployment rate.
Compare with (118.9). Equating marginal products \(s\,a\,(n + n_0)^{a-1}\) across the two states gives \((n_{\text{high}} + n_0)/(n_{\text{low}} + n_0) = 2^{1/(1-a)}\), so for these economies the formula applies to \(n + n_0\) rather than to \(n\).
What happens to unemployment as the returns to labor mobility rise, and why?
Solution
Only the construction of R changes, and we add a function that averages employment within each demand state.
def two_state_dr(a, ρ=0.9, s_lo=1.0, s_hi=2.0, β=0.9, n0=20.0, y_max=3000):
    "Two demand states, output s n^a, so R = s a (n + n0)^(a-1)."
    P = np.array([[ρ, 1-ρ], [1-ρ, ρ]])
    s = np.array([s_lo, s_hi])
    y = np.arange(y_max + 1)
    R = s[:, None]*a*(y[None, :] + n0)**(a - 1)
    R[:, 0] = 0.0
    return Model(P=P, s=s, y=y, R=R, β=β)

def employment_by_state(m, r):
    "Mean employment in each demand state under the invariant distribution."
    emp = np.minimum(m.y[None, :], r['n_bar'][:, None])
    return (r['ψ']*emp).sum(axis=1) / r['ψ'].sum(axis=1)

def report(name, m, r, a=None, n0=None):
    "One row of the table; a and n0 are given only for the decreasing returns schedules."
    En = employment_by_state(m, r)
    shifted = '--' if n0 is None else f"{(En[1] + n0)/(En[0] + n0):.2f}"
    formula = '--' if a is None else f"{2**(1/(1 - a)):.2f}"
    print(f"{name:>18}{En[0]:>9.1f}{En[1]:>9.1f}{En[1]/En[0]:>8.2f}{shifted:>10}"
          f"{formula:>10}{100*r['unemployment']/r['workforce']:>8.2f}%")

print(f"{'technology':>18}{'E[n|lo]':>9}{'E[n|hi]':>9}{'ratio':>8}{'+n0 ratio':>10}"
      f"{'formula':>10}{'u rate':>9}")
report('this lecture', two, market_outcomes(two, equilibrium_λ(two, μ)))
for a in (0.4, 0.6, 0.75):
    m_a = two_state_dr(a)
    r_a = market_outcomes(m_a, equilibrium_λ(m_a, μ, lo=0.01, hi=80.0))
    report(f'output s n^{a}', m_a, r_a, a=a, n0=20.0)
        technology  E[n|lo]  E[n|hi]   ratio +n0 ratio   formula   u rate
      this lecture     26.0     68.3    2.63        --        --    4.75%
    output s n^0.4     32.0     64.4    2.01      1.62      3.17    3.60%
    output s n^0.6     23.0     71.6    3.11      2.13      5.66    5.40%
   output s n^0.75     10.0     81.1    8.11      3.37     16.00    7.98%
The same doubling of demand moves mean employment by a factor of about \(2.6\) under this lecture’s schedule and by a factor of about \(8\) when output is \(s\,n^{0.75}\).
Mean employment is not the employment threshold \(\bar n\).
In this two-state economy a market in the high state never reaches \(\bar n(s_{\text{high}})\): arrivals fill it only to \(\bar y(s_{\text{high}})\), and in the first period of an upturn it still holds the \(\bar n(s_{\text{low}})\) workers it carried out of the low state, so mean employment in the high state is \(\rho\, \bar y(s_{\text{high}}) + (1-\rho)\, \bar n(s_{\text{low}})\).
For part 2, the formula is a frictionless benchmark, and the model responds less than it in every case, by a margin that grows with \(a\).
That is what a one-period moving friction should do.
A frictionless economy would move workers until marginal products were equal across markets; here workers move only until arriving is worth \(\lambda\), arrivals stop at \(\bar y(s_{\text{high}})\) because demand may fall back, and an upturn takes a period to be met at all.
Ratios of \(n\) alone are a poor guide in these economies, because when low-state employment is small the shift \(n_0\) is large relative to it.
a = 0.75
for n0 in (10.0, 20.0, 40.0):
    m_a = two_state_dr(a, n0=n0)
    En = employment_by_state(m_a, market_outcomes(m_a, equilibrium_λ(m_a, μ, lo=0.01, hi=80.0)))
    ratio = En[1]/En[0] if En[0] > 0 else np.inf
    print(f"n0 = {n0:4.0f}:  E[n|lo] = {En[0]:5.1f},  ratio of n = {ratio:6.2f},"
          f"  ratio of n + n0 = {(En[1] + n0)/(En[0] + n0):.2f}")
n0 =   10:  E[n|lo] =  16.0,  ratio of n =   4.77,  ratio of n + n0 = 3.32
n0 =   20:  E[n|lo] =  10.0,  ratio of n =   8.11,  ratio of n + n0 = 3.37
n0 =   40:  E[n|lo] =   0.0,  ratio of n =    inf,  ratio of n + n0 = 3.25
The ratio of \(n\) swings from finite to infinite as \(n_0\) rises, while the ratio of \(n + n_0\), which is what the technology governs, barely moves.
The ratio of about \(26\) that Baley et al. [2025] compute for Alvarez and Veracierto’s parameters comes from the frictionless formula with an exponent of about \(4.3\), larger than any exponent here, and a slightly bigger shock: it measures what their technology would do to a shock of that size if reallocation were instantaneous.
As for part 3, unemployment rises with the returns to labor mobility, from \(3.6\) to \(8.0\) percent across these economies, and it does so for other values of the shift \(n_0\) as well.
That is not a coincidence and it is not a cost.
Unemployment in this model is the time workers spend moving, and the more there is to gain by moving, the more of them move.
This is the sense in which the quantity Baley et al. [2025] are after governs everything else: an economy with high returns to labor mobility will show a lot of reallocation, will keep reallocating even when a layoff tax makes it expensive, and will record the unemployment that goes with it.